Programmers keep small failures from bringing down high-performance computing systems
High-performance computers have the potential to make large problems a lot easier to solve. But there is one stumbling block common to all big computing systems: they crash — a lot.
A small team of programmers at Sandia California may have figured out how to keep small failures from bringing down whole systems and costing users a lot of time and money, earning a coveted R&D 100 award in the process.
Fraught with failure
“There are periods when these systems fail frequently,” computer scientist Hemanth Kolla said. “When that happens, simulations usually have to stop, and then they have to restart once the system is back online. Usually the whole calculation just stops, goes back to the last safe checkpoint, and is resumed. What we’ve done with Fenix is design a library that handles failures more gracefully, more swiftly, and enables any large calculation to keep progressing.”
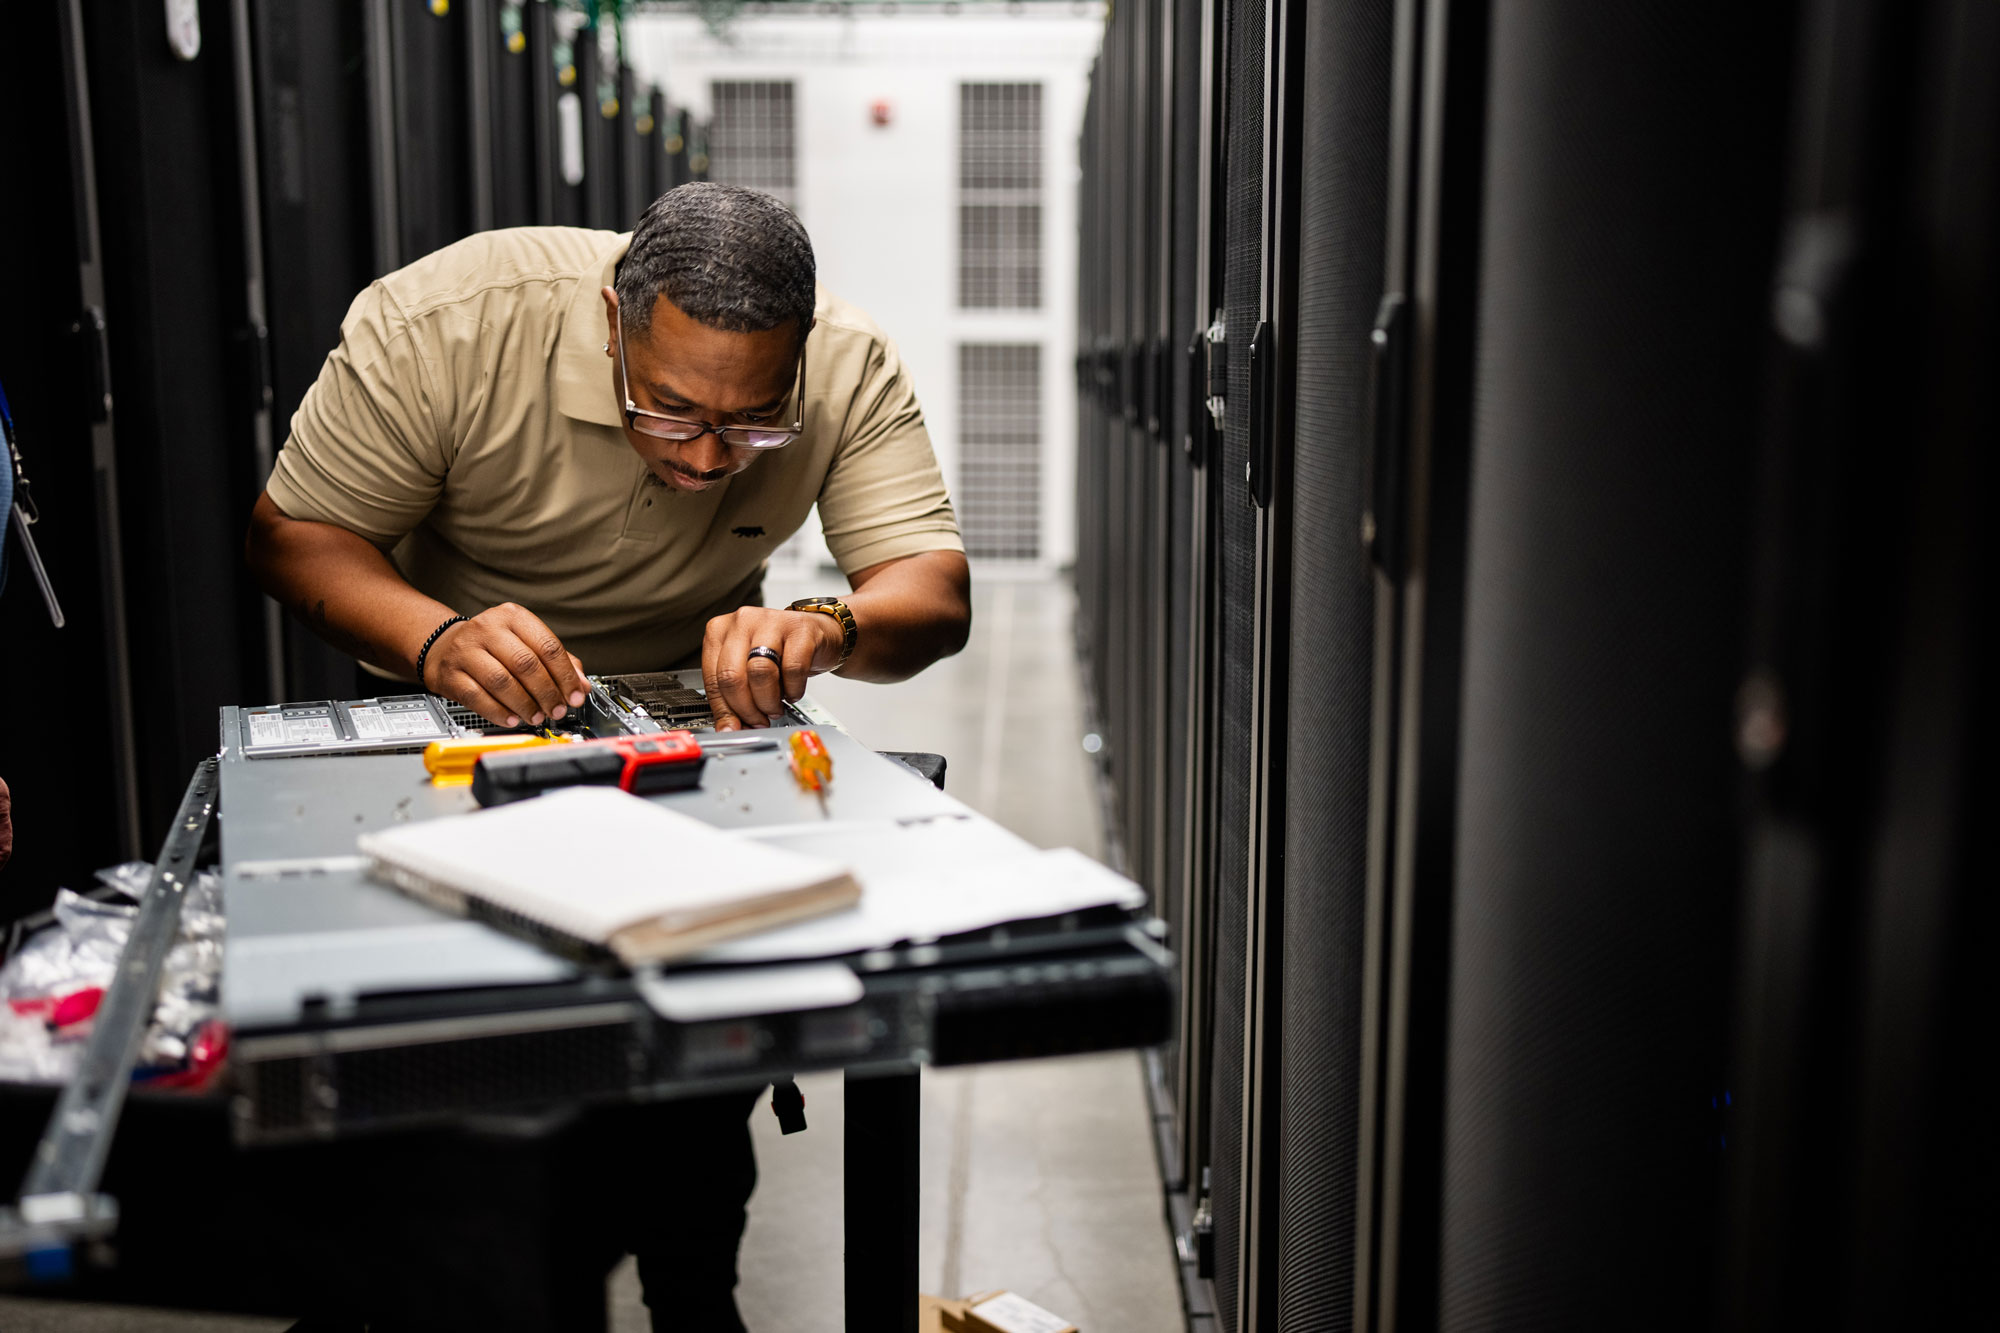
Hemanth oversaw the latest version of Fenix, designed by a Sandia team led by postdoctoral researcher Matthew Whitlock. It runs on three components: a process recovery component, a data recovery component and a message recovery component.
“The traditional way that applications recover from a failure is that as soon as it happens, we actually shut down every single one of that application’s processes across the entire computing cluster,” Matthew said.
“All of the other nodes are having to lose their progress because of this heavy-handed way of responding to a failure,” Hemanth added.
It is not just the act of shutting down and starting back up that encumbers high-performance computers with serious backlogs.
“We destroy all of the memory that they had and then we relaunch everything,” Matthew said. “It now has to do a whole bunch of work to reinitialize everything, and that initialization on really large-scale runs can take up to three minutes.”
“Which means that you have 10,000 nodes all trying to write to the exact same parallel file system that might have a dozen or more servers,” Hemanth said. “So, there’s this huge bottleneck.”
Time is money
If a high-performance computer is failing every 15 minutes and it takes about three minutes to write a checkpoint, another three to reinitialize all the processes and three more to recover from the checkpoint, that is about nine minutes every 15 just to recover from failures. With the frequency of errors, that means just as you recover from one, another one is close at hand.
“HPC simulations are at the center of Sandia’s missions,” Hemanth said. “Scientific computing is at the heart of Department of Energy science activities. There’s any number of scientific applications that run large simulations. Beyond DOE, AI data centers are the thing now for private industry. We’re talking of machines or large data centers from Meta and Google and X that are hundreds of thousands of computing nodes, all of which have reported similar behavior. Their systems face frequent failures of the order of tens of minutes.”
When failures are so common across computers that not only power the government, but also daily life for millions of Americans, the best solution is one that is easy to implement.
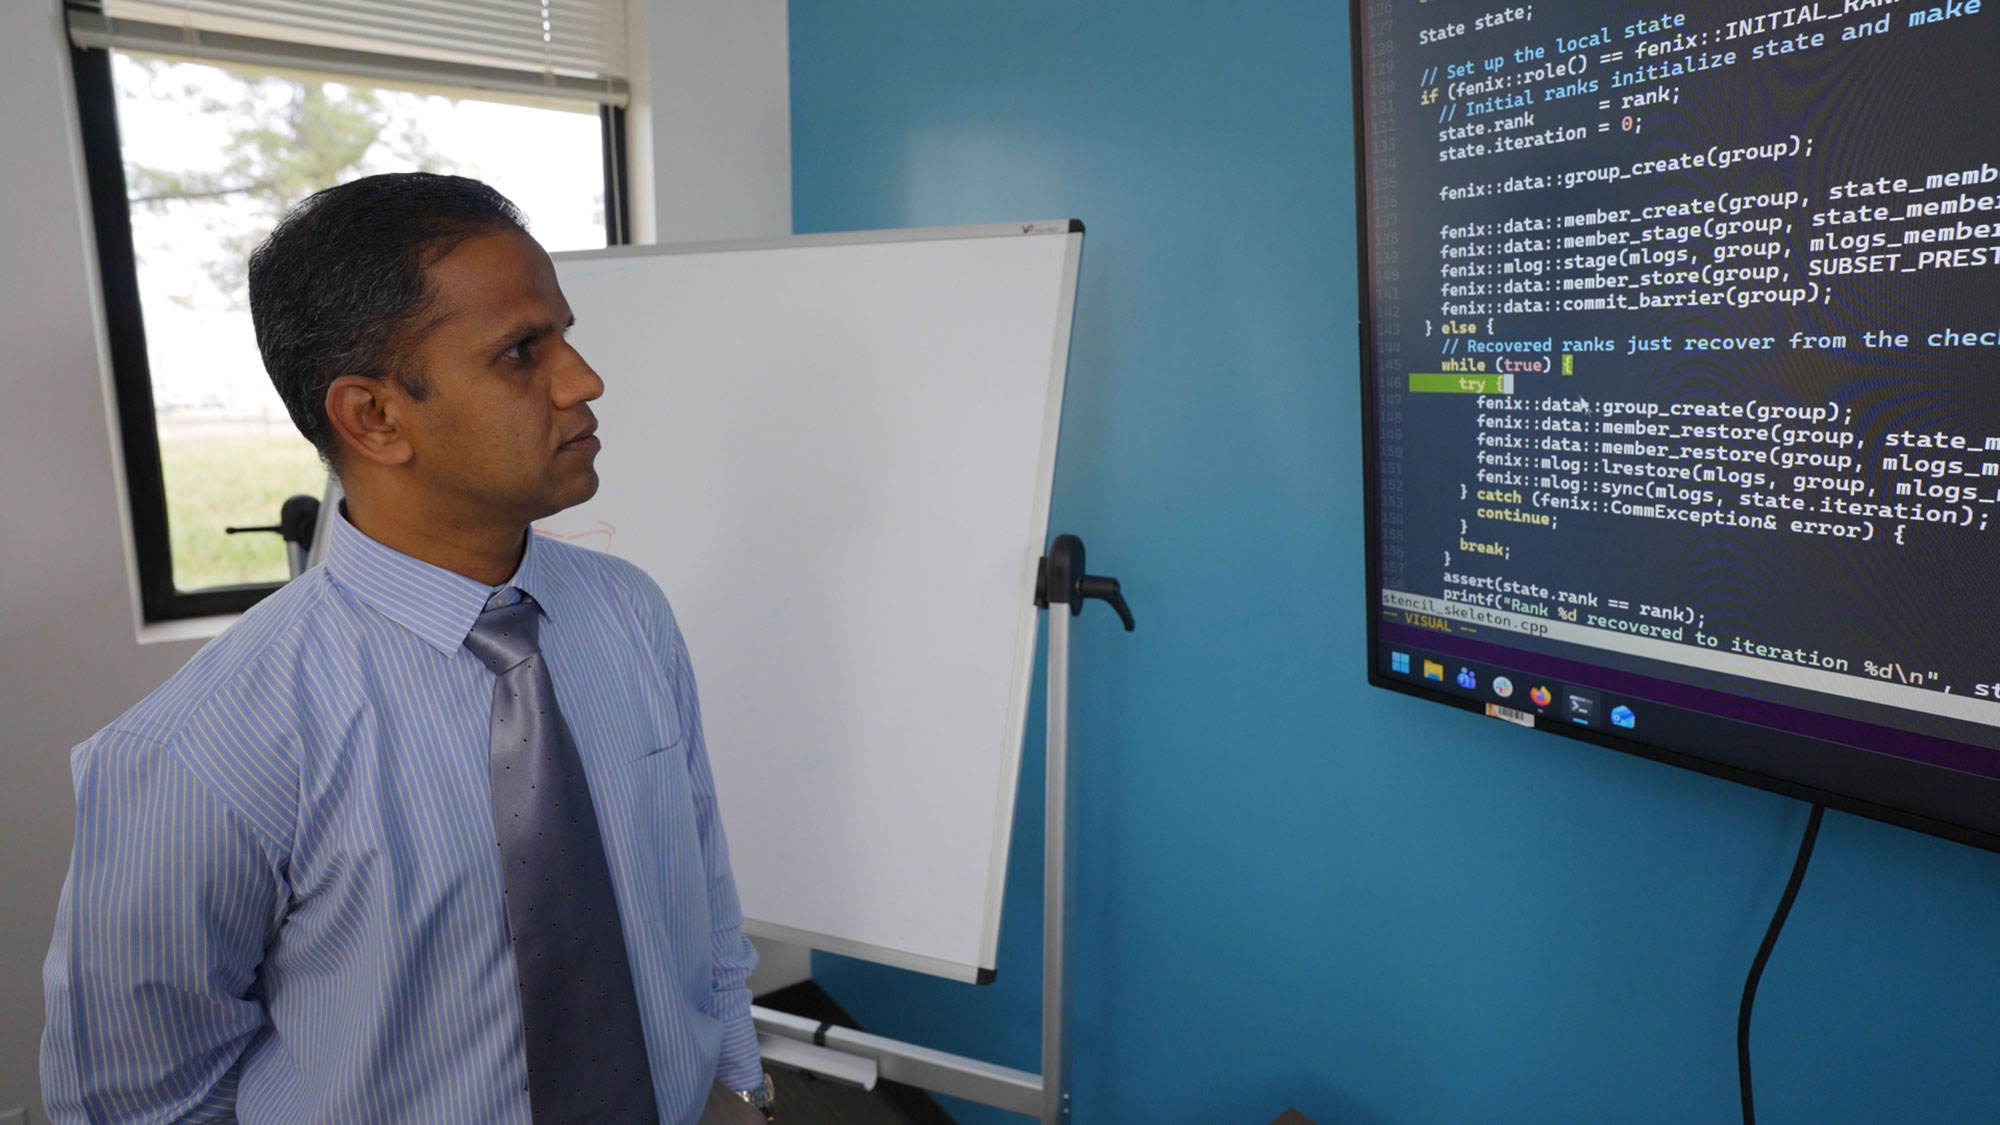
(Photo by Bryn Whisenand)
“Fenix is allowing applications to only respond locally, so only the node that has faced a failure, and those nodes that are immediately affected by the failure, have to roll back,” Hemanth explained. “This allows all of the other nodes to continue making progress.”
Fenix can also help processes checkpoint their work locally, so they don’t have to start from the very beginning every time. Fenix backs up these checkpoints in small process groups, instead of requiring much more time-consuming parallel file system access. This is only possible because Fenix recovery avoids destroying all the application’s processes.
“It takes a few extra processes when we first initialize everything, and we’ll set them off to the side,” Matthew said. “When a process fails, Fenix steps in and it uses these brand-new, very low-level functions to rebuild the application’s communicator, which is the way that it actually messages back and forth between processes and manages collective operations.”
In other words, the nodes that produce a computing error can catch back up more quickly. It is exactly why R&D World selected Fenix for the R&D 100 Awards, because of its “novelty, impact and practical applications.”
Checkpoint shortcut
The process has been around since 2015, but only recently the team has been able to use the pseudo-local recovery, or checkpointing, model.
“It’s also only fairly recently that we have been able to simplify the integration into an application to the degree that it actually feels viable to say, ‘Let’s put this into a system that has a million lines of code,’” Matthew said.
Hemanth pointed out that a growing sector of the American economy has been key to driving their progress forward so quickly.
“Companies that run AI data centers want to train larger and larger models,” he said. “They want to push that boundary to even larger models, and training is the single most expensive thing in AI. So, companies spend a lot of time, money, resources, including power, to train these massive models.”
That training can take weeks, sometimes months, and when you include delays from frequent failure, the process can prove enormously expensive.
“So if AI data centers adopt a similar local recovery type approach, they will be having a huge cost savings,” Hemanth said.
That cost is borne not just in dollars and cents, but also in energy usage, cooling, work hours and more.
“The biggest cost of running AI data centers is power,” Hemanth said. “Every minute you have to keep it running, you’re consuming insane amounts of power. Time directly impacts operating costs. If you can do a training run in only an 18th of the time, you can translate that into the amount of watts saved and to a reduction in operating costs. The same applies to HPC simulations that the DOE lab uses as well.”
When your main applications for high-performance computing are millions or billions of lines of code, and integrating Fenix is less than a thousand lines of code, it does not take an HPC to calculate the cost savings inherent in Sandia’s latest triumph.